Fairness, Bias and the Appeal That Never Comes
A courier in Bologna who booked an evening delivery session and then joined a strike would lose points in the ranking that decided when she could book work next. The ranking did not record why a rider had stayed away; it recorded only that she had. Drivers in the United Kingdom whose accounts were deactivated for suspected fraud were told of the decision, and the court that later examined their cases could not establish that any person had weighed their side of the story. Neither case involves a manager who disliked anyone. Both involve a rule nobody had tested for its effect on groups and a route of appeal that led nowhere. This chapter stages the debate on fairness, bias and contestability in algorithmic management. It concerns M2 Evaluation, because scores, rankings and performance figures are where bias enters, and M3 Consequence, because pay, promotion, deactivation and access to work are where it does its damage and where contest matters most.
The chapter builds on AI Threat, Chapter 12, which examined discrimination in automated judgement and how a disparate-impact test runs in a release pipeline, and Chapter 11 of that volume, which followed public authorities whose automated systems went wrong (44, Nordqvist, 2026). It takes over conclusion F31, that in public authorities the line between decision support and automated decision is drawn in the data model and the audit log, with a reasons log for every case (AI Governance, Chapter 17) (41, Nordqvist, 2026). What is new is the workplace: the person affected is an employee or a person performing platform work, and the relationship continues after the decision. Chapter 27 designs contestability in full; this chapter sketches only what the debate requires.
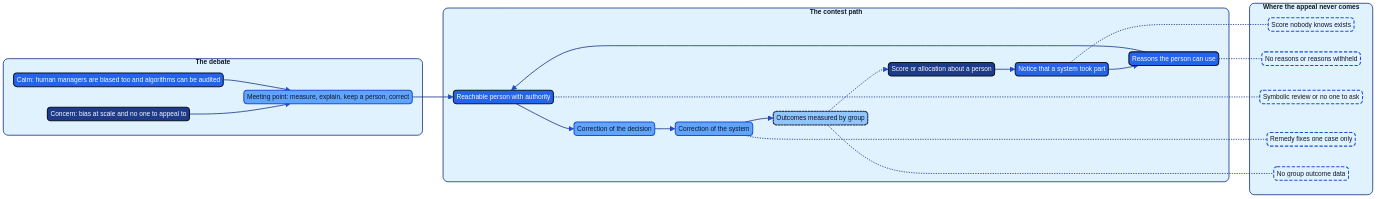
Figure 12.1: The contest path and the points where it fails; both sides of the debate agree that fairness depends on measuring outcomes by group, giving reasons, keeping a reachable person and correcting the system as well as the case.
Documented bias
The evidence on bias in systems that evaluate people is uneven. Some of it comes from controlled audits outside the workplace, some from litigation about platforms, and some from large data sets that show an outcome gap without a biased rule. Each kind shows something different, and the debate later in this chapter depends on keeping them apart.
Audits outside the workplace
Two audits, examined in AI Threat, Chapter 12, set the pattern (44, Nordqvist, 2026). Buolamwini and Gebru evaluated three commercial gender-classification systems on a benchmark balanced by gender and skin type and found error rates of up to 34.7 per cent for darker-skinned women against a maximum of 0.8 per cent for lighter-skinned men (166, Buolamwini & Gebru, 2018): aggregate accuracy can hide large failures for the group least represented in the data. Obermeyer and colleagues found that a commercial algorithm used to select patients for extra care predicted health-care costs rather than illness; because less was spent on Black patients with the same needs, Black patients at a given risk score were considerably sicker, and remedying the disparity would have raised their share among those receiving additional help from 17.7 to 46.5 per cent (169, Obermeyer et al., 2019). A performance system that predicts what is easy to record, such as throughput or hours logged, in place of what the organisation values carries every difference in opportunity that shapes the record.
The Bologna ranking
The first workplace case is a court order. On 31 December 2020 the Tribunale di Bologna, Labour Section, ruled on a claim by unions against Deliveroo Italia. Riders booked work sessions through a self-service system in which a personal score set the order of access: riders with the highest scores could book from 11 a.m. on Sundays, the others at 3 p.m. or 5 p.m. from the slots that were left. A rider who booked a session and neither cancelled it at least 24 hours in advance nor logged in within 15 minutes of its start suffered a reduction in that score, because the day counted among the fourteen working days used for the statistics. The court found that the system did not distinguish a rider who stayed away for trivial reasons from one whose absence rested on legally protected grounds, such as taking part in a strike, and held the booking system to be indirectly discriminatory under Legislative Decree No. 216/2003, which transposes Directive 2000/78/EC into Italian law; the claimants had also raised illness and the care of a child. The court awarded the unions EUR 50,000 in damages and ordered the decision to be published (196, Purificato, 2021) (54, Council of the European Union, 2000).
What the case shows is narrower and more useful than "the algorithm discriminated". A rule that looks neutral, rewarding reliability, became a mechanism that penalised the exercise of a right, because the system's definition of reliability had no field for a reason. That is an M2 Evaluation design choice with M3 Consequence effects, since the score governed access to work.
The rideshare earnings gap
The second workplace study points the other way. Cook and colleagues examined labour supply and earnings among more than a million Uber drivers in the United States and documented a gender earnings gap of roughly 7 per cent in a setting where pay is set by a formula that does not know the driver's sex. They explained the gap entirely by three factors: experience on the platform, preferences over where to work, largely driven by where drivers live and to a lesser extent by safety, and driving speed. They found no differential effect of preferences for particular hours and no evidence of customer discrimination (139, Cook et al., 2021).
The study is often read as evidence that algorithmic pay is fair. It shows something more precise: a rule that rewards experience, location and speed can produce an outcome gap between groups even when the rule treats every individual identically, and the gap can be decomposed only because the platform's data are complete enough to do so. Whether a gap of that kind is acceptable is a question for the people who set the rule, not one the data answer.
Hiring
Chapter 7 treats automated hiring, where Raghavan and colleagues documented what vendors of pre-employment assessments disclosed about validation and bias mitigation (172, Raghavan et al., 2020); a deployer that must show fairness to a works council often depends on what its provider chose to publish.
Why bias enters
Bias in management systems rarely starts with an intention. Barocas and Selbst observed that data can let algorithms inherit the prejudices of earlier decision-makers or reproduce pre-existing patterns of exclusion, and that because the result is usually unintended it can be unusually hard to locate or to explain to a court (158, Barocas & Selbst, 2016). Four mechanisms matter most at work.
The definition of good performance. Every M2 Evaluation system encodes a target. The Bologna score defined reliability as attendance without reasons; a sales score that counts complaints defines quality as the absence of complaints, which depends on the market and the customers a person is given. The target is a management decision, usually made by whoever configures the system.
Proxies. Availability, postcode, continuous service and the hours a person can work correlate, in many workforces, with sex, age, disability or caring responsibilities. Obermeyer's cost proxy is the documented example of a convenient variable carrying a disparity into every decision that uses it.
Historical data. A model trained on past managerial decisions learns them. Cowgill's model shows that an algorithm can remove biases in historical decisions only if those decisions were noisy enough to provide variation; otherwise it will codify or exacerbate them (171, Cowgill, 2019). Whether a model trained on a company's promotion history is fairer than its managers depends on how consistent they were, which nobody usually knows.
Feedback loops. AI Act Article 10(2)(f) requires providers of high-risk systems to examine possible biases "especially where data outputs influence inputs for future operations" (1, European Union, 2024). At work the loop is ordinary: the handler who receives fewer complex claims gains less experience, scores lower on the indicators that reward it, and receives fewer still.
These mechanisms explain why a system can pass every individual check and still disadvantage a group, and why the only reliable detection is to measure outcomes by group.
The appeal that never comes
Bias that is measured can be corrected; bias that is never noticed persists, and the person best placed to notice it is usually the person affected. Contest is therefore the organisation's most direct error signal as well as a right. It fails in four recurring ways.
No notice. A person cannot contest a score she does not know exists. In Mode 0 Ambient AI, analytics in licensed software can produce productivity scores that nobody registered as a management system. Under AI Act Article 26(11), deployers of high-risk systems listed in Annex III that make or assist in making decisions related to natural persons must inform those persons that they are subject to the system (1, European Union, 2024).
No reasons. The Bologna score had no field for a reason on the worker's side, and many systems have none on the organisation's side either: the output is a number, and the record, if there is one, says only that it crossed a threshold.
No one to ask. In April 2023 the Gerechtshof Amsterdam examined Uber's deactivation of drivers for suspected fraud. Because the relevant information lay largely with Uber, the platform bore a heavier duty to substantiate its denial that the decisions were solely automated. Applying the Article 29 Working Party's guidelines, which require oversight to be meaningful rather than a token gesture and to be carried out by someone with the authority and competence to change the decision, the court held that Uber had not made it plausible that notes made by one to three employees of its risk team in Kraków were more than a purely symbolic act, and found it hard to see how such an examination could be made without hearing the drivers (67, Gerechtshof Amsterdam, 2023) (61, Article 29 Data Protection Working Party, 2018).
A remedy that fixes one case. When an appeal succeeds, the decision is reversed and the rule stays. A contest that never reaches the owner of the system leaves the organisation as uninformed as before.
How people experience such decisions has been measured. In Lee's online experiment, four managerial decisions were attributed either to an algorithm or to a human manager. For tasks requiring mechanical skills the two were perceived as equally fair; for tasks requiring human skills, algorithmic decisions were perceived as less fair and less trustworthy and evoked more negative emotion, which participants linked to the algorithm's perceived lack of intuition and to the dehumanising experience of being evaluated by a machine (165, Lee, 2018). Binns and colleagues found in three experiments that people apply much the same dimensions of justice to algorithmic decisions as to human ones, raising arbitrariness, generalisation and indignity; the study takes its title from a participant: "It's reducing a human being to a percentage" (164, Binns et al., 2018). Neither study observed real workplaces over time. Both show that the absence of a person to answer is part of what people judge.
When contest fails at scale
Public authorities have supplied the clearest evidence of what happens when bias and failed contest combine at scale. The two Dutch cases concern citizens rather than employees, and AI Threat, Chapter 11, treats them as failures of the automated state (44, Nordqvist, 2026); their mechanism, a score, a consequence and a contest route that did not work, is the one this book is concerned with.
SyRI. On 5 February 2020 the District Court of The Hague held that the legislation governing SyRI, which linked data held by public bodies to generate risk reports on possible fraud, failed to comply with Article 8(2) of the European Convention on Human Rights because its application was insufficiently transparent and verifiable. The court could not verify how the risk model was generated and found it hard to see how a person could defend against a risk report. SyRI had been applied only in neighbourhoods labelled problem districts, and the court found a risk that it would inadvertently create links based on bias, such as lower socio-economic status or an immigration background, which could not be assessed without insight into the indicators and the model. A human check of the results did not compensate, because the final selection was not public and those affected were not told how it was made (192, District Court of The Hague, 2020).
The childcare-benefits affair. In December 2020 the Dutch House of Representatives' inquiry committee published Ongekend onrecht, unprecedented injustice. It concluded that fundamental principles of the rule of law had been violated, by the benefits service, the legislature and the administrative courts; that the group approach, the "all or nothing" approach to recovery and the treatment of intent and gross negligence had grossly violated the principle that justice be done to individual circumstances; and that parents had been wrongly branded as deliberate fraudsters. The report describes the service's risk-classification model as a self-learning model with several dozen indicators, whose selections were checked manually, and records the data protection authority's finding that its use of applicants' nationality, at least from March 2016 to October 2018, was unlawful and discriminatory (191, Tweede Kamer, 2020).
Both cases combined a score whose logic those affected could not see, a process that treated its output as presumptively right, and a contest route that could not reach the reasons. A performance score used in a reorganisation or a screening model that filters applicants can reproduce that structure on a smaller scale, and a human check that cannot see the logic adds little.
What the law requires of reasons and review
Chapters 21 and 22 set out the legal frame. Five provisions shape this debate; each is stated as an organisational implication, not legal advice.
GDPR Article 22 gives a data subject the right not to be subject to a decision based solely on automated processing with legal or similarly significant effects; where such a decision is permitted by contract or explicit consent, the controller must provide at least the right to human intervention, to express a point of view and to contest (5, European Union, 2016). The Amsterdam judgment shows that a review which is not meaningful does not take a decision out of Article 22.
The SCHUFA judgment of 7 December 2023 held that a credit agency's automated probability value is itself an automated individual decision where a third party draws strongly on it to establish, implement or terminate a contract; where the value plays a determining role, its establishment counts as the decision (63, CJEU, 2023). A performance score that managers follow in practice may be treated the same way, so measure how often managers depart from a score before calling it advice.
The Dun & Bradstreet judgment of 27 February 2025 held that under Article 15(1)(h) the controller must explain, in an intelligible form, the procedure and principles actually applied to the person's data, and that information claimed as a trade secret goes to the supervisory authority or court for balancing (65, CJEU, 2025). A provider's secrets do not end the employer's duty to explain.
AI Act Article 86 gives a person affected by a deployer's decision based on the output of a high-risk system listed in Annex III, which includes point 4 on employment and workers' management, the right to clear and meaningful explanations of the system's role in the procedure and the main elements of the decision, where the decision has legal or similarly significant effects the person considers adverse to health, safety or fundamental rights (1, European Union, 2024). Article 86 sits in Chapter IX, which applies from 2 August 2026; the deployer duties of Article 26 that make an explanation possible apply to Annex III systems from 2 December 2027, after the Digital Omnibus moved the date for Chapter III, Sections 1 to 3 (2, European Union, 2026).
Equality law defines indirect discrimination as an apparently neutral provision, criterion or practice that puts persons with a protected characteristic at a particular disadvantage unless objectively justified by a legitimate aim pursued by appropriate and necessary means, and shifts the burden of proof to the respondent once facts are shown from which discrimination may be presumed: Directive 2000/78/EC, Articles 2(2)(b) and 10; Directive 2006/54/EC for sex; in Germany, § 3(2) and § 22 of the General Act on Equal Treatment (54, Council of the European Union, 2000) (56, European Union, 2006) (74, Germany, 2006). The burden of proof is decisive: once a gap is shown, the employer must justify the rule behind it, and can do so only with outcome data it has already collected.
Two further instruments show the direction. The Platform Work Directive requires platforms to evaluate, with workers' representatives and at least every two years, the impact of automated decisions including on equal treatment, and to modify or discontinue a system with a high risk of discrimination (Article 10); it gives a right to an explanation, a contact person with authority, written reasons for decisions such as suspending an account, and a review answered within two weeks, with correction of the decision and of the system (Article 11) (47, European Union, 2024). Its transposition deadline is 2 December 2026. And the Digital Omnibus inserted Article 4a into the AI Act, allowing deployers of high-risk systems, exceptionally and under strict safeguards, to process special categories of personal data where strictly necessary for bias detection and correction, while creating no obligation to do so (2, European Union, 2026).
The debate
The documented cases, the mechanisms and the law leave a real disagreement about what algorithmic management does to fairness. Both positions are held by serious people with evidence.
The case for concern
Algorithmic management reproduces historical bias at scale, through proxies nobody chose, and replaces the manager a person could appeal to with a process that gives no reasons. Those who hold this view point first to scale: a biased manager affects a team, a biased rule affects every person it scores until someone measures it. O'Neil's account of models that are opaque, applied at scale and damaging to those they score, and Eubanks's study of automated systems that profile and punish poor people in public services, both locate the harm in the uniformity with which a flawed rule is applied (159, O'Neil, 2016) (167, Eubanks, 2018).
They point second to opacity. The Bologna score and SyRI reached a court because unions and civil-society organisations brought the cases, and even then the court in The Hague could not see how the model worked. In most workplaces nobody brings a case, and the worker who suspects her score has no data on how others were scored; the burden-of-proof rules help only someone who can first show a pattern.
They point third to the disappearance of the person. Lee's participants found algorithmic evaluation of human work less fair and dehumanising, and in the Amsterdam case notes made far away were not shown to be more than a symbolic act (165, Lee, 2018) (67, Gerechtshof Amsterdam, 2023). Green surveyed 41 policies requiring human oversight of government algorithms and concluded that people are often unable to perform the oversight assumed, so that the requirement legitimises flawed systems and lets vendors and agencies avoid accountability (178, Green, 2022). The case for concern concludes that consequence decisions should not be shaped by scores people cannot see, and that every promise of auditability should be judged by whether audits happen.
The case for calm
Human managers are documented to discriminate, algorithms can be tested for disparate impact and corrected, and a consistent rule can be fairer than many inconsistent ones. Those who hold this view start with the baseline. Bertrand and Mullainathan answered job advertisements in Boston and Chicago with fictitious CVs carrying names that sounded either African American or White; White-sounding names received 50 per cent more callbacks, and a better CV helped them far more (156, Bertrand & Mullainathan, 2004). No algorithm was involved. The comparison for an AI boss is the managers an organisation actually has.
They point next to evidence that discretion can make outcomes worse. Hoffman, Kahn and Li studied job testing across 15 firms employing low-skilled service workers and found that managers who appeared to hire against the test's recommendations ended up with worse average hires, which suggests that they often overruled because they were biased or mistaken (163, Hoffman et al., 2018). Cowgill's model shows when training on noisy human decisions can reduce their bias (171, Cowgill, 2019), and in Lee's experiment people judged algorithmic decisions on mechanical tasks as fair as human ones (165, Lee, 2018).
Their strongest point is auditability. A rule in software can be run on every case and its outcomes compared by group; the judgement of three hundred line managers cannot. The rideshare gap could be decomposed because the platform held complete data (139, Cook et al., 2021), and the Bologna rule could be litigated because its mechanics could be described to a court. A biased manager is retrained one at a time; a biased rule, once found, is corrected for everyone at once. The case for calm concludes that algorithms should be tested, published and corrected in ways human judgement never was, not kept out of management.
Where the positions meet
Both positions accept that the comparison is with real managers, not ideal ones; that a rule's fairness shows in its outcomes, not its design, and that outcomes must be measured by group and at intersections, where Gender Shades found the largest failures (166, Buolamwini & Gebru, 2018); that a person facing a consequence decision needs usable reasons and a reachable person with authority to change it; and that a correction which leaves the rule in place corrects nothing. What remains is empirical and local: whether a given system, in a given workforce, over a given period, does better or worse than the practice it replaced. That has an answer only where someone collected the data.
What can be done
Workers can ask in writing whether a system took part in a decision about them and use the rights that exist: access to the logic under GDPR Article 15(1)(h), the safeguards of Article 22(3) where a decision is solely automated, and the explanation under AI Act Article 86 for decisions based on Annex III systems. A contest that states what the person believes is wrong and asks for the reasons is more useful than one that asks only for reversal.
Line managers can refuse to treat a score as a decision: record for every M3 Consequence decision what they considered besides the score and where they departed from it, and pass every successful contest to the system's owner rather than fixing the case quietly.
Employers can test every system that feeds M2 Evaluation or M3 Consequence for disparate impact on every release, following F16, that review is triggered by change (41, Nordqvist, 2026), keep contestation records linked to the delegation profile, and contract with providers for the evidence testing needs.
Workers' representatives can make outcome data by group, aggregated so that no individual can be identified, a standing item of the works agreement or collective agreement. BetrVG § 75(1) already obliges employer and works council to ensure that every person in the establishment is treated according to law and equity and that disadvantage on grounds such as age, sex, disability or trade-union activity does not occur (9, Germany, 2001). On the Swedish model, the Discrimination Act requires employers, in cooperation with employees, to investigate risks of discrimination in working conditions, pay, recruitment, promotion and training, analyse their causes, act and follow up (Chapter 3, Sections 2, 4, 5 and 11) (76, Sveriges riksdag, 2008). A disparate-impact test of a management system is such active measures done properly.
Supervisors can enforce Articles 15 and 22 of the GDPR as the Court has read them, prepare for Article 86 complaints, and treat the Platform Work Directive's evaluation and review duties as the benchmark of a reasonable employer.
Practical guide: Running a disparate-impact test on a management system with the representatives
Purpose. Find out whether a system that evaluates people or allocates work, pay or opportunities disadvantages a group, explain why, correct it and tell the workforce.
Roles. The system owner, HR analytics, the data protection officer, the works council or union representatives, two or three line managers who use the system and, through the representatives, the workers affected.
Steps.
- Agree the question with the representatives four weeks before the test: the system, its delegation profile, the management functions it serves and the outcomes that matter to the people affected. Record the agreement in the works agreement's annex or the negotiation minutes.
- Choose the groups. Start with characteristics held lawfully for HR purposes (age band, part-time status, contract type, site, sex where held) and at least one intersection. Process special categories only where strictly necessary under AI Act Article 4a, with the data protection officer's written assessment.
- Set a reporting floor of 20 people per cell and merge or suppress smaller cells, so that the test cannot become a means of monitoring individuals.
- Measure outcomes. For each favourable outcome compute each group's rate relative to the reference group with a 95 per cent bootstrap interval. Treat a lower bound below 0.80 as a trigger for investigation, not a finding of discrimination; adapt the threshold where the collective agreement sets another.
- Test the proxies and the target: how strongly each input predicts group membership, and whether the target could differ between groups for reasons unrelated to performance.
- Find the cause within 20 working days of a trigger, decide whether it is objectively justified, and record the justification or correction in an AI Decision Record.
- Correct the system and list the cases the disparity affected so that their deciders can review them.
- Report the full results to the representatives and a one-page summary to the workforce within 30 days.
- Repeat on every release, on a change in the workforce or the rules, when contests cluster, and at least every six months.
Definition of done. The test is versioned with the system, the representatives have the results and the workforce the summary, every trigger has a recorded cause and decision, affected cases are listed, and the next run is scheduled.
Worked example: A disparate-impact test of claims allocation at Hansa Mutual
The following record is illustrative. Hansa Mutual's claims-triage agent allocates claims to individual handlers at Level 3 Bounded for M1 Direction under the delegation profile DLG-HM-CTA-01, and its throughput figures feed M2 Evaluation at Level 1 Assisted. Because the allocation of complex claims shapes the experience on which promotion to senior handler depends, the group tests it as a management system. The test is reported to the Konzernbetriebsrat under the group works agreement KBV-IT-2024, and AIDR-0653 records the group's decision to run such tests on every release of a management system.
disparate_impact_test:
  id: DIT-HM-CTA-01
  status: illustrative
  system: claims-triage agent, allocation to claims handlers
  delegation_profile: DLG-HM-CTA-01
  management_functions: [M1 Direction, M2 Evaluation]
  decision_records: [AIDR-0651, AIDR-0653]
  works_agreement: KBV-IT-2024
  owner: group head of claims operations
  reviewers: [Konzernbetriebsrat IT committee, group data protection officer]
  period: 2026-Q3
  population: claims handlers allocated by the agent in Germany
  groups:
    attributes: [handler_group, age_band, part_time_status]
    intersections: [[part_time_status, sex]]
    reference: full_time
    min_cell_size: 20
    special_categories: none
  outcomes:
    - name: share_of_complex_claims
      favourable: true
      metric: rate_ratio
      trigger_if_lower_bound_below: 0.80
    - name: claims_per_available_hour
      metric: rate_ratio
      trigger_if_outside: [0.90, 1.10]
    - name: reassigned_by_team_leader
      metric: rate_ratio
      trigger_if_outside: [0.80, 1.25]
  results:
    - outcome: share_of_complex_claims
      group: part_time
      ratio: 0.71
      interval_95: [0.64, 0.78]
      triggered: true
    - outcome: share_of_complex_claims
      group: [part_time, women]
      ratio: 0.69
      interval_95: [0.60, 0.79]
      triggered: true
    - outcome: claims_per_available_hour
      group: part_time
      ratio: 1.04
      triggered: false
    - outcome: share_of_complex_claims
      group: age_band_55_plus
      ratio: 0.97
      triggered: false
  cause: >
    Allocation rule CTA-R-14 offers complex claims only to handlers with
    two consecutive working days left in the week, which most part-time
    handlers rarely have.
  justification_found: false
  correction:
    rule_change: complex claims may span shifts with a recorded handover
    retest: 2027-Q1
    affected_cases: senior-handler promotion files 2025-2026 flagged for review
  reported_to_works_council: 2026-12-08
  workforce_summary_due: 2027-01-07
The record does not say that anyone discriminated. It shows that a rule written for continuity of claims handling put part-time handlers, most of them women in this population, at a particular disadvantage in access to the work that leads to promotion, without a justification that would pass the test of appropriate and necessary means under Directive 2006/54/EC and the General Act on Equal Treatment (56, European Union, 2006) (74, Germany, 2006). The correction changes the rule, and the promotion files are flagged because the disparity may already have shaped M3 Consequence decisions, which belong to the people who took them.
Verdict
M2 Evaluation. That systems which evaluate people carry bias through targets, proxies, historical data and feedback loops is observable: in classifier audits, in a health algorithm affecting millions of patients, in a court order on a platform's ranking and in a public risk model that processed nationality unlawfully. That outcome gaps arise under rules treating every individual identically is also observable. A general rate of bias in workplace evaluation is not documented, because few employers measure outcomes by group.
M3 Consequence. That contest fails without notice, reasons or a reachable person is observable in the Amsterdam judgment, SyRI and the childcare-benefits affair. That the law will make contest more reachable is expected: the Platform Work Directive's transposition deadline is 2 December 2026, and the deployer duties for Annex III systems that support explanation under Article 86 apply from 2 December 2027; how courts will apply Article 86 to workplace decisions is not yet known. That audited algorithms will in general become fairer than the managers they assist is speculation, supported by the logic of auditability and the evidence on human bias but not yet by long-run workplace evidence.
What can be influenced is what decides which position proves right in a given organisation: whether outcomes are measured by group, whether representatives see them, whether every consequence decision has a person who gives reasons and can change it, and whether contests reach the owner of the system. Fairness is not a property an AI boss has or lacks; it is one an organisation demonstrates, release by release, or cannot claim.
Across the degrees of delegation
| Degree of delegation | Where bias enters | Where contest fails | Minimum safeguard |
|---|---|---|---|
| Level 0 Advisory | The score frames the manager's judgement | The worker may not know the score exists | Register the score; tell the worker; test outcomes |
| Level 1 Assisted | The manager follows the recommendation | Reasons are the system's, not the manager's | Record departures; manager gives own reasons |
| Level 2 Supervised | Approvals become routine | Review is symbolic if the approver cannot see the logic | Oversight-quality metric; explanation to the approver |
| Level 3 Bounded | The bounds themselves encode the disparity | No individual decision to contest, only a pattern | Disparate-impact test on every release; contest patterns reported |
| Level 4 Autonomous | Not used for M3 Consequence | Not applicable | Never delegated for consequences |
In Mode 0 Ambient AI the first safeguard is to discover the feature at all; a score in licensed software that nobody registered cannot be tested or contested until it is entered in the delegation register. Systems deployed as Mode 4 Built AI applications give the organisation the data to test; procured ones require that the contract does.
Nordvik Region and Hansa Mutual
At Nordvik Region, Ingrid Halvorsen commissions a fairness review of ShiftWise open-shift offers by contract type, recorded in AIDR-0606, because part-time and hourly home-care staff depend on extra shifts for their income and the offers are made at Level 3 Bounded under DLG-NR-ROS-01. The review reuses the Region's practice from the benefits-triage system, where the gate DIT-NR-CR-01 runs on every release of the claims ranker (AI Threat, Chapter 12) (44, Nordqvist, 2026). Offers go to everyone who opted in, as the profile requires, but a competence filter for delegated medication administration excludes most hourly staff in the Strandvik unit from about a third of them, because few have completed the course. The filter is justified by patient safety; the gap in access to the course is not. Mikael Strand and the union agree training places, and the review is repeated as part of the Region's active measures. The paused screening pilot (AIDR-0601) remains the Region's own example of an appeal that could not be answered.
fairness_review:
  id: DIT-NR-ROS-01
  status: illustrative
  system: ShiftWise open-shift offers
  delegation_profile: DLG-NR-ROS-01
  decision_record: AIDR-0606
  owner: Ingrid Halvorsen, HR director
  reviewers: [union for municipal and care workers, data protection officer]
  groups: [permanent_full_time, permanent_part_time, hourly]
  min_cell_size: 20
  outcome: offers_received_per_opted_in_person
  result: {group: hourly, ratio: 0.66, triggered: true}
  cause: competence filter for delegated medication administration
  justification: filter justified by patient safety; access to the course is not
  correction: training places for hourly staff in home care
  retest: 2027-06
At Hansa Mutual, the allocation test goes to the Konzernbetriebsrat under KBV-IT-2024, and Jana Petersen's team in Hamburg is among the first to receive complex claims under the corrected rule. Thomas Brandt asks for the same test on the sales-performance score, which feeds variable pay at Level 0 Advisory under DLG-HM-SPS-01, after CNT-HM-0001, a sales employee's contestation of a quarterly score (Chapter 27), shows how much the complaints indicator depends on how complaints are attributed and how far complaint rates differ between markets; market is added as a group. Nordvik, bound to give reasons in every case, finds its gaps in eligibility rules around the algorithm; Hansa, with more systems that score people, finds them in the algorithm's own rules and must show seven national arrangements the same evidence.
Summary
The chapter staged the debate on fairness, bias and contestability, which concerns M2 Evaluation, where scores and rankings carry bias, and M3 Consequence, where pay, promotion, deactivation and access to work turn it into harm. The evidence runs from audits of facial classification and a health algorithm that used cost as a proxy for need, through the Bologna court's finding that a delivery platform's ranking penalised riders who went on strike, to a rideshare earnings gap that arose under a rule treating every individual identically.
Bias enters through the definition of good performance, proxies, historical decisions and feedback loops, so it can be found only by measuring outcomes by group. The appeal never comes without notice, reasons, a reachable person with authority, or a remedy that reaches the rule; the Amsterdam deactivation judgment, SyRI and the childcare-benefits affair show those failures at growing scale. GDPR Articles 15 and 22 as the Court has read them, AI Act Article 86, the burden of proof in equality law and the Platform Work Directive point the same way: reasons, a person and correction.
The case for concern and the case for calm meet on four conditions: measure outcomes by group, give reasons, keep a reachable person and correct the system as well as the case. Documented bias and failed contest are observable, stronger rights to explanation and review are expected, and audited algorithms becoming fairer than managers is speculation. What organisations can do now is test with their representatives on every release and publish what they find.
Chapter 13 turns from what the AI boss decides to what it must see in order to decide: surveillance at work and its chilling effect on voice, which concerns M2 Evaluation and M5 Care.
Sources
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. The Architecture as Code Series, Book 5. (44, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 2. (41, Nordqvist, 2026)
- Buolamwini, J. & Gebru, T. (2018). Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification. Proceedings of the 1st Conference on Fairness, Accountability and Transparency, PMLR 81. (166, Buolamwini & Gebru, 2018)
- Obermeyer, Z., Powers, B., Vogeli, C. & Mullainathan, S. (2019). Dissecting racial bias in an algorithm used to manage the health of populations. Science, 366(6464). (169, Obermeyer et al., 2019)
- Purificato, I. (2021). Behind the Scenes of Deliveroo's Algorithm: in the Blindness of "Frank" its Discriminatory Potential. Italian Labour Law e-Journal, 14(1). (196, Purificato, 2021)
- Council of the European Union (2000). Council Directive 2000/78/EC establishing a general framework for equal treatment in employment and occupation. Official Journal of the European Communities. (54, Council of the European Union, 2000)
- Cook, C., Diamond, R., Hall, J. V., List, J. A. & Oyer, P. (2021). The Gender Earnings Gap in the Gig Economy: Evidence from over a Million Rideshare Drivers. The Review of Economic Studies, 88(5). (139, Cook et al., 2021)
- Raghavan, M., Barocas, S., Kleinberg, J. & Levy, K. (2020). Mitigating bias in algorithmic hiring: evaluating claims and practices. Proceedings of FAT* 2020. (172, Raghavan et al., 2020)
- Barocas, S. & Selbst, A. D. (2016). Big Data's Disparate Impact. California Law Review, 104(3). (158, Barocas & Selbst, 2016)
- Cowgill, B. (2019). Bias and Productivity in Humans and Machines. Upjohn Institute Working Paper 19-309. (171, Cowgill, 2019)
- European Parliament and Council of the European Union (2024). Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). Official Journal of the European Union. (1, European Union, 2024)
- Gerechtshof Amsterdam (2023). Judgment of 4 April 2023, ECLI:NL:GHAMS:2023:793 (drivers and App Drivers & Couriers Union v Uber). Rechtspraak.nl. (67, Gerechtshof Amsterdam, 2023)
- Article 29 Data Protection Working Party (2018). Guidelines on Automated individual decision-making and Profiling for the purposes of Regulation 2016/679 (WP251rev.01). (61, Article 29 Data Protection Working Party, 2018)
- Lee, M. K. (2018). Understanding perception of algorithmic decisions: Fairness, trust, and emotion in response to algorithmic management. Big Data & Society, 5(1). (165, Lee, 2018)
- Binns, R., Van Kleek, M., Veale, M., Lyngs, U., Zhao, J. & Shadbolt, N. (2018). 'It's Reducing a Human Being to a Percentage': Perceptions of Justice in Algorithmic Decisions. Proceedings of CHI 2018. (164, Binns et al., 2018)
- District Court of The Hague (2020). Judgment of 5 February 2020, NJCM et al. v. the State of the Netherlands (SyRI), ECLI:NL:RBDHA:2020:1878. Rechtspraak.nl. (192, District Court of The Hague, 2020)
- Tweede Kamer der Staten-Generaal, Parlementaire ondervragingscommissie Kinderopvangtoeslag (2020). Ongekend onrecht. The Hague. (191, Tweede Kamer, 2020)
- European Parliament and Council of the European Union (2016). Regulation (EU) 2016/679 (General Data Protection Regulation). Official Journal of the European Union. (5, European Union, 2016)
- Court of Justice of the European Union (2023). Judgment of 7 December 2023, OQ v Land Hessen (SCHUFA Holding (Scoring)), Case C-634/21, ECLI:EU:C:2023:957. (63, CJEU, 2023)
- Court of Justice of the European Union (2025). Judgment of 27 February 2025, CK v Dun & Bradstreet Austria GmbH and Magistrat der Stadt Wien, Case C-203/22, ECLI:EU:C:2025:117. (65, CJEU, 2025)
- European Parliament and Council of the European Union (2026). Regulation (EU) 2026/1744 (Digital Omnibus on AI). Official Journal of the European Union. (2, European Union, 2026)
- European Parliament and Council of the European Union (2006). Directive 2006/54/EC on the implementation of the principle of equal opportunities and equal treatment of men and women in matters of employment and occupation (recast). Official Journal of the European Union. (56, European Union, 2006)
- Federal Republic of Germany (2006). Allgemeines Gleichbehandlungsgesetz (AGG). Gesetze im Internet. (74, Germany, 2006)
- European Parliament and Council of the European Union (2024). Directive (EU) 2024/2831 on improving working conditions in platform work. Official Journal of the European Union. (47, European Union, 2024)
- O'Neil, C. (2016). Weapons of Math Destruction: How Big Data Increases Inequality and Threatens Democracy. Crown. (159, O'Neil, 2016)
- Eubanks, V. (2018). Automating Inequality: How High-Tech Tools Profile, Police, and Punish the Poor. St. Martin's Press. (167, Eubanks, 2018)
- Green, B. (2022). The flaws of policies requiring human oversight of government algorithms. Computer Law & Security Review, 45. (178, Green, 2022)
- Bertrand, M. & Mullainathan, S. (2004). Are Emily and Greg More Employable Than Lakisha and Jamal? A Field Experiment on Labor Market Discrimination. American Economic Review, 94(4). (156, Bertrand & Mullainathan, 2004)
- Hoffman, M., Kahn, L. B. & Li, D. (2018). Discretion in Hiring. The Quarterly Journal of Economics, 133(2). (163, Hoffman et al., 2018)
- Federal Republic of Germany (2001). Betriebsverfassungsgesetz (BetrVG). Gesetze im Internet. (9, Germany, 2001)
- Sveriges riksdag (2008). Diskrimineringslag (2008:567). (76, Sveriges riksdag, 2008)