The Human in the Chair: Oversight That Is Real, Not Rubber-Stamped
Every chapter of this book has ended its recommendations with a person: the unit manager who approves the roster, the recruiter who decides on the applicant, the team leader who can reassign the claim. This chapter asks when that person is a decider and when a signature attached to a system's output. It sets out what the research on automation bias measured, separates oversight of a system, which can be sampled, from the human decision in an individual case, which cannot be delegated, and defines two artefacts: the oversight record and the oversight-quality metric. It concerns M3 Consequence, where every decision about a person has a named human decider, and M2 Evaluation, because evaluations feed consequences and because measuring overseers is itself an evaluation that must be designed with care. It touches M1 Direction, where rosters and allocations are approved or reassigned at volume. It answers open question Q9: whether oversight can be real when the overseer has hundreds of decisions an hour, and how an organisation would know that it has become a rubber stamp.
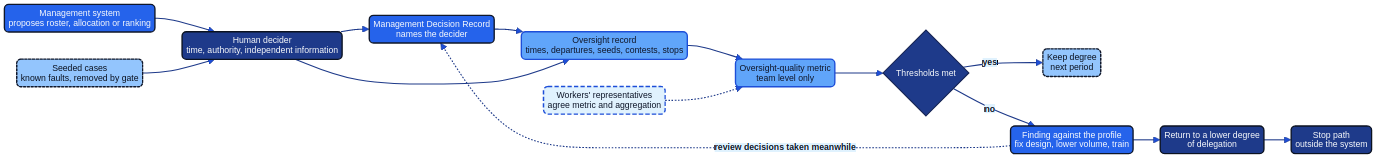
Figure 26.1: The oversight loop. The metric tests the design, not the people in it, and a failing metric returns the system to a lower degree of delegation.
The chapter builds on five conclusions of the earlier volumes: human oversight is designed, not declared, and approvals given in seconds signal rubber-stamping (F21), with stop rights named in advance (F19) (AI Governance, Chapters 10, 13 and 21) (41, Nordqvist, 2026); approval quality is measured by time, rejections and reversals, agreed with works councils first and reported in aggregate (F52; AI Red Team, Chapters 6 and 15) (43, Nordqvist, 2026); reliance on AI reduces checking and erodes the skills of those who must catch its errors, answered by drafting first, seeded-error drills and a team-level oversight-quality metric (F66; AI Threat, Chapters 6 and 14) (44, Nordqvist, 2026); and verifying AI proposals requires seeded errors, an oversight-quality metric and review that does not start from the AI's answer (F76; The Transformed Security Architect, Chapter 14) (46, Nordqvist, 2026).
The human in the loop, examined
A requirement that a human be involved is the most common safeguard in the law and policy of algorithmic management, and the least tested. Ben Green surveyed 41 policies that prescribe human oversight of government algorithms and found two flaws: the evidence suggests that people are unable to perform the oversight the policies assume, and the policies therefore legitimise faulty algorithms, provide a false sense of security and let vendors and agencies shirk accountability. He proposed institutional oversight instead, in which the organisation justifies with evidence both the algorithm and the form of human oversight, and submits that justification to democratic review before adoption (178, Green, 2022).
What a nominal human looks like at volume was reported from a health insurer in the United States. ProPublica and The Capitol Forum reported in March 2023 that, according to company documents, Cigna's doctors had denied over 300,000 payment requests in two months through a system that let them reject claims without opening the patient file, spending an average of 1.2 seconds on each; Cigna called the reporting "biased and incomplete" and said the description of its process was incorrect (245, Rucker et al., 2023). The case is not about employees, and its facts are disputed. It shows the arithmetic: a person who signs a decision in a second has not read it, whatever the process documentation says.
Data protection law already treats such a person as absent. The Article 29 Working Party's guidelines, endorsed by the European Data Protection Board, state that a controller cannot avoid Article 22 of the GDPR by fabricating human involvement: someone who routinely applies automatically generated profiles without any actual influence on the result leaves the decision based solely on automated processing. Oversight must be meaningful rather than a token gesture, carried out by someone with the authority and competence to change the decision, who considers all the relevant data (61, Article 29 Data Protection Working Party, 2018). In SCHUFA the Court of Justice held that where a third party draws strongly on an automatically established score to establish, implement or terminate a contractual relationship, establishing the score is itself an automated decision under Article 22(1), since a narrower reading would risk circumventing Article 22 and leave a lacuna in legal protection (63, CJEU, 2023). As an organisational implication, whether a management decision was human is answered by what the human did, not by whose name is on it, and the employer needs records that show what the human did.
Elish described the cost to the person in the chair: responsibility misattributed to a human who had limited control over an automated system, a moral crumple zone that protects the system at the expense of the nearest operator (170, Elish, 2019). Chapter 4 answered that the name must carry the means of deciding. This chapter turns the means into conditions that can be designed and checked.
Automation bias and selective adherence
The research does not show that people always defer to machines. It shows that reliance depends on attention, workload, framing and prior belief, and that it can be shaped by design.
Skitka, Mosier and Burdick found in a simulated monitoring task that participants with an automated aid made errors of omission, missing events it did not flag, and of commission, following its recommendations when they were wrong (155, Skitka et al., 1999). Parasuraman and Manzey's review found that complacency occurs under multiple-task load, when manual tasks compete with the automated one for attention, and that automation bias produces both kinds of error, occurs in naive and expert participants alike, cannot be prevented by training or instructions and affects teams as well as individuals (25, Parasuraman & Manzey, 2010). Two findings matter for an employer: training is necessary but does not protect by itself, and the overseer's other work is part of the risk. A unit manager approving a roster between a staff shortage and a family's complaint is in the multiple-task condition the review describes.
Alon-Barkat and Busuioc ran three experiments in the Netherlands on public-sector decisions. With 605 and then 904 participants they found no automation bias: advice labelled algorithmic was not followed more than equivalent advice from a human expert. They did find selective adherence: advice aligned with group stereotypes was adopted more readily, from either source. With 1,345 civil servants, shortly after the Dutch childcare benefits scandal, they found neither, which they attribute to heightened awareness of discrimination after the scandal (179, Alon-Barkat & Busuioc, 2023). An overseer may follow a ranking because it confirms what the overseer expected of a group, so the record of departures must show not only how often overseers depart but for whom.
The error also runs the other way. Dietvorst, Simmons and Massey found in five studies that people who saw an algorithm forecast became less likely to choose it over an inferior human forecaster, even after seeing it outperform the human, because they lost confidence in it faster after the same mistake (157, Dietvorst et al., 2015). Logg, Minson and Moore found that lay people adhered more to advice they believed came from an algorithm, while experienced professionals relied on it less, which hurt their accuracy (168, Logg et al., 2019). A design that only counts acceptances misses half the problem.
Bainbridge's ironies of automation complete the picture: automation leaves the operator the tasks the designer could not automate, asks the operator to monitor a system the operator no longer runs, and removes the practice needed to take over when it fails (24, Bainbridge, 1983). A team leader whose team has been allocated work by an agent for two years, as Chapter 19 described, is Bainbridge's operator. Real oversight must keep the overseer able to oversee.
What makes oversight real
Chapter 4 listed the capabilities a named decider needs. The six conditions below turn them into properties of a management system that can be designed, recorded and tested.
- Time per decision. The volume per overseer leaves the time each decision deserves, measured from opening the case to recording the decision, and planned in working time rather than added on top of it.
- Authority to deviate. The overseer may decide against the proposal without prior approval and without justifying a departure more heavily than an acceptance. The AI Act requires providers of high-risk systems to enable overseers "to decide, in any particular situation, not to use the high-risk AI system or to otherwise disregard, override or reverse the output", under Article 14(4)(d) (1, European Union, 2024).
- Information independent of the system. The overseer sees the grounds of the proposal and also what the system did not produce: the person's own request, the sickness list from the HR system, the full application rather than the rank. Article 14(4)(a) requires that overseers can understand the system's capacities and limitations and detect anomalies, and Article 14(4)(c) that they can correctly interpret its output; neither is possible from the output alone.
- A measured deviation rate. The organisation knows how often overseers depart, with what reasons and for whom, and has agreed what rate would signal rubber-stamping and what rate an unfit system. Article 14(4)(b) requires that overseers remain aware of the tendency to over-rely on output, "in particular for high-risk AI systems used to provide information or recommendations for decisions to be taken by natural persons". Awareness that is never measured cannot be shown.
- Consequences that do not punish deviation. Departing costs the overseer nothing beyond a written reason, and oversight figures are never used to evaluate or discipline the overseer. For platform work, Article 10(2) of the Platform Work Directive requires that overseers have the competence, training and authority necessary, including for overriding automated decisions, and enjoy protection from dismissal, disciplinary measures and other adverse treatment when they exercise their functions (47, European Union, 2024).
- A stop path. Someone can stop the system, outside it, in the time the harm allows, as Chapter 20 assigned. Article 14(4)(e) requires that overseers can interrupt a high-risk system through a "stop" button or a similar procedure that brings it to a halt in a safe state.
Article 26(2) requires deployers to assign oversight to natural persons with the necessary competence, training and authority, as well as the necessary support, and Article 26(6) to keep the logs under their control for at least six months unless other law provides otherwise (1, European Union, 2024); for Annex III systems both apply from 2 December 2027 under Article 113 as amended by the Digital Omnibus (2, European Union, 2026). The six conditions are what "competence, training, authority and support" means for a single decision, and the logs hold the evidence of conditions 1 and 4. Where the GDPR permits a decision based solely on automated processing because it is necessary for a contract or based on explicit consent, Article 22(3) requires at least the right to obtain human intervention, to express a point of view and to contest the decision (5, European Union, 2016). Read with the Working Party's guidance and SCHUFA, a signature without influence may make a decision solely automated, and the intervention a worker can then demand must come from someone able to change the outcome. The oversight record shows both.
Oversight of the system and the decision in the case
Two human roles share the word "oversight", and the confusion explains much of what Green found.
Oversight of the system asks whether the system as a whole proposes what it should: whether rosters respect rest rules, allocations follow the agreed rules, rankings disadvantage a group. This role can be sampled. A team leader need not inspect every allocation the claims-triage agent makes to know, from seeded cases, reassignments and a weekly sample, whether it allocates within its rules. It is how Level 3 Bounded is made safe for M1 Direction: approval moves from the action to the rules and the sample, as AI Red Team, Chapter 6, concluded (F51) (43, Nordqvist, 2026).
The decision in the case is a decision about one person: whether this applicant is invited, whether this employee's variable pay is reduced. It cannot be sampled. A sample shows that ninety-five decisions out of a hundred were sound; it gives the other five people no decision. For M3 Consequence the decision in the case is required in every case, and oversight of the system is added to it, never substituted for it.
The distinction gives each delegation profile a test. At Level 3 Bounded the organisation designs oversight of the system and does not pretend that a person reviews every instance. At Level 2 Supervised and below every case passes a person, and time, information and authority per case are the design variables. Where cases pass a person who does not influence them, as in Hansa Mutual's Dutch sales unit in Chapter 8, where 97 per cent of pay proposals matched the score band at a median of 48 seconds, the observed degree is higher than the recorded one: the score was "decisive in practice". For M1 Direction that calls for honest reclassification and oversight of the system; for M3 Consequence, where Level 3 Bounded and above are excluded, the use stops until the decision in the case is real again.
The oversight record
The oversight record answers, for one delegation profile and one period, four questions: who oversaw, what they saw, what they did and with what authority. The Management Decision Record of Chapter 25 holds the individual decision and names its decider; the contestation record of Chapter 27 holds a challenge; the delegation profile holds the intended degree; the oversight record holds the evidence of the observed degree. It contains the design (class, profile, overseer role, authority, independent information, maximum volume, planned time), the figures aggregated as agreed with the representatives, the classification of the observed degree using Chapter 8's practice test, and the findings and actions with the AI Decision Record that records them. It names no overseer in its figures: it tests the design, and those who designed the class answer for what it shows.
Worked example: the oversight record for ShiftWise roster approval at Nordvik Region
Illustrative. Unit managers in Nordvik Region's home care approve every four-week roster that ShiftWise drafts, at Level 2 Supervised under DLG-NR-ROS-01. The first home-care wave went live in early 2027 in seven units, Mikael Strand's Strandvik unit among them. Ingrid Halvorsen, the HR director, owns the profile.
# oversight/OVR-NR-ROS-2027-1.yaml (illustrative)
id: OVR-NR-ROS-2027-1
profile: DLG-NR-ROS-01
class: NR-M1-ROSTER-APPROVE            # DRF-NR-01
recorded_degree: Level 2 Supervised
period: {from: 2027-02-01, to: 2027-05-31}
scope: home-care wave 1, seven units
owner: role:hr-director                 # Ingrid Halvorsen
design:
  overseer: role:unit-manager
  authority: change any assignment or route without approval; reason recorded in the MDR
  independent_information: [staff requests in PeopleCore, unit sickness list, client care plans]
  planned_time_per_roster: PT2H
  seeded_faults: two per unit per period, removed by the publication gate if missed
metric: OQM-NR-ROS-01
reported_to: [central work-environment committee, union for municipal and care workers, union for nurses and midwives]
aggregation: all approvers in scope; minimum five; no figure per unit manager
figures:
  approvers: 7
  rosters_approved: 26
  median_minutes_open_to_approve: 12
  approvals_under_2_minutes: 5
  rosters_changed_before_approval: 15
  rest_rule_flags_raised: 31
  flags_closed_by_bulk_acknowledgement: 11
  seeded_faults: {placed: 14, found: 10, rate: 0.71}
  contestations: {received: 1, decision_changed: 1, record: CNT-NR-0001}
thresholds:                             # agreed in negotiation, reviewed yearly
  seeded_catch_min: 0.85
  median_minutes_min: 10
  approvals_under_2_minutes_max: 0
  bulk_flag_closure_max: 0
classification: Level 2 Supervised in most approvals; nearer Level 3 Bounded in five
findings:
  - Five approvals under two minutes; four rosters had flags closed in bulk
  - Seeded-fault catch below threshold
  - Four of seven approvers had not completed the oversight module
actions:
  decision_record: AIDR-0630
  measures:
    - Approval blocked until each rest-rule flag has its own resolution
    - Publication gate confirms every seeded fault is removed
    - Two hours per roster planned in the unit manager's schedule
    - AI literacy and oversight training before a unit goes live
next_record: OVR-NR-ROS-2027-2
The figures do not say which unit managers approved quickly, and Ingrid Halvorsen does not ask. The finding is against the profile: a screen that let eleven rest-rule flags be closed with one click, and a wave that went live before its managers were trained. AIDR-0630 records the response listed under actions, and adds a trigger: if the seeded-fault catch stays below 0.85 for two consecutive periods, the roster class for the units concerned returns to Level 1 Assisted, in which the manager draws the roster and ShiftWise checks it.
Measuring oversight quality
An oversight-quality metric is a small set of figures, agreed in advance, that shows whether the six conditions hold in practice (F52, F66). Each figure answers one question.
- Time to decision shows whether the case could have been read. It is a floor, not a target; a minimum-time gate is avoided because it invites waiting rather than reading.
- Departures with reasons show whether the overseer influences outcomes. A floor signals acceptance without reading; a ceiling signals an unfit system or the aversion Dietvorst and colleagues measured. Reasons are read, not only counted, and departures are broken down by the groups the selective-adherence finding makes relevant, at an aggregation that protects the people concerned.
- Seeded-case catch shows whether overseers find errors known to be there. Seeds are synthetic or placed in drafts that are never acted on, and a gate removes any seed that is missed, so no real person is affected.
- Reversals on contest show whether oversight let through what the person affected could see.
- Stops and pauses show whether the authority of condition 6 is used, and used without penalty.
The defaults in this book are those Hansa Mutual already uses for OQM-HM-CLM-01, the team-level metric for review of agent output in Chapter 16's weekly routine: seeded-case catch at least 0.85, rejection rate at least 0.02 and median approval at least 30 seconds for a draft letter. A four-week roster or a consequence decision needs a floor measured in minutes.
Measuring the review, not the reviewers
The metric is built from logs of who opened which case, when, and what they decided, and the overseer is an employee. Measured carelessly, oversight becomes monitoring of managers and recruiters, and teaches them to look busy rather than to decide. In Germany the works council co-determines the introduction and use of technical equipment designed to monitor employees' behaviour or performance, under BetrVG §87(1) no. 6 (9, Germany, 2001), and approval logs are such data; elsewhere the duty to negotiate and data minimisation lead to the same place. The book draws three rules from F52 and F66.
- Aggregate by default. Report for a group of at least five overseers. Handlers' review is reported per team; team leaders' or unit managers' oversight per department or wave, because a team leader is alone in the team.
- Separate the uses. Oversight figures are never an input to the overseer's own M2 Evaluation or to any M3 Consequence decision about the overseer, and the delegation profile lists that as an excluded use. A breach is a finding against the design, which the profile owner must correct, as Chapter 20 required.
- Let each overseer see their own figures. Nobody above the overseer sees them, except the individual decision record when that decision is contested.
Practical guide: Setting up an oversight-quality metric for a management system with the representatives' agreement
Purpose. Establish a metric that shows whether oversight of a management system is real, reported at a level the representatives accept and never used to evaluate the overseers.
Roles. The owner of the delegation profile leads; two overseers help design the measures; the operator or supplier provides the logs; the data protection officer checks minimisation, access and retention; the works council or unions negotiate or agree; a worker affected by the system reads the plan for clarity.
Steps.
- Name the class and the human role. For each class in the decision-rights file, record whether the role is oversight of the system (Level 3 Bounded) or the decision in the case (Level 2 Supervised or lower). Every M3 Consequence class needs the decision in the case.
- Write the six conditions for each class: planned time, authority, independent information, expected deviation rate, excluded uses of the overseers' figures, stop path.
- Choose the measures: time to decision, departures with reasons, seeded-case catch, reversals on contest, stops used, and class-specific ones such as flags closed without resolution or applications opened before rejection.
- Set floors and ceilings. Defaults: seeded catch 0.85; departures 0.02 for routine drafts and 0.05 for consequence inputs; median time 30 seconds for a short draft, 10 minutes for a four-week roster, 2 minutes for an adverse M3 decision; a departure rate above 0.30 triggers a review of the system.
- Design the seeds. Default two per overseer group per month; overseers know seeds exist but not which; a gate removes missed seeds before they can affect anyone.
- Agree aggregation and access: minimum group of five, own figures only, logs kept for the metric and the contestation period and at least as long as Article 26(6) requires where it applies.
- Negotiate or agree at least four weeks before the decision, under the procedure that applies: BetrVG §87(1) no. 6 in Germany, negotiation before the decision in Sweden, the consent right in the Netherlands. Record the agreement in the profile.
- Run and report an oversight record each quarter (monthly for the first six months) to the representatives and the profile owner.
- Act on findings as described under "When oversight fails", recorded as an AI Decision Record.
Definition of done. Every class in the delegation register has a recorded human role, written conditions and an agreed metric with thresholds; the profile lists oversight figures as an excluded input to M2 and M3; the first oversight record has been read; and seeds have been shown never to reach a person. Adapt the defaults to the collective agreement, the works agreement and the organisation's risk appetite.
Designing volume
The book's answer to Q9 has three parts.
At hundreds of decisions an hour, there is no decision in the case, and the design must say so. At three hundred an hour each decision has twelve seconds, enough to check a field and not to read an application, a roster or a claim. Such a class is at Level 3 Bounded in practice whatever its profile says. For M1 Direction that can be legitimate, with oversight of the system designed for it. For M3 Consequence it never is, and the volume must change.
Volume is set by the owner. The number of decisions multiplied by the minimum time each deserves gives the overseer hours the class needs, and those hours are planned. Hansa Mutual's decision-rights file caps recruiter reviews of TalentLens rankings at twelve an hour. A cap is real only if something gives when demand exceeds it: more recruiters, a posting that closes at the volume the team can read, or a slower process. Where the oversight record shows that reading was not possible, Chapters 4 and 20 placed accountability with whoever set the volume, and the record is how that is shown.
Fewer decisions. Triage helps when it routes by need for judgement and by direction of effect: a roster without flags needs less of the manager's time than one with three breaches, and proposals favourable to the person can be accepted with sampling while adverse ones go to a person with time. The strongest reduction is not to produce decisions that should not exist. Hansa's empty list of M3 decisions that throughput figures may feed, in Chapter 20, removed a stream of consequence decisions before any overseer had to examine one.
Competence and authority
Article 4 of the AI Act, as amended by the Digital Omnibus, requires deployers to take measures to support the AI literacy of staff dealing with the operation and use of AI systems on their behalf, taking into account the context and the persons on whom the systems are used (2, European Union, 2026). Article 26(2) asks more of overseers of a high-risk system. Read with Article 14(4)(a) to (c), the overseer of a management system needs to know what the system uses and does not see, how to read its output, which errors it is known to make, and what automation bias and selective adherence are, with the seeded-case results of the overseer's own group as evidence that they apply there too. Because training alone does not prevent automation bias, the seeds, the time and the independent information come with the training, not after it.
Competence also decays. A unit manager who has approved ShiftWise rosters for two years without drawing one cannot judge whether a draft is reasonable, which is why Chapter 19 reserved hand-planned weeks. A falling seeded-case catch is a signal for that craft programme, and the programme is a precondition for keeping a class at Level 2 Supervised.
Authority is the condition employers most often omit, as Chapter 21 observed, and it is practical as well as formal. A screen on which accepting is one click and departing needs a form and a sign-off teaches acceptance; so does a target that assumes proposals are accepted, and so does a culture that treats a reversal on contest as the overseer's failure rather than the system working. This book recommends for every overseer of a management system the protection that Article 10(2) of the Platform Work Directive gives overseers of platform work, written into the delegation profile and the works agreement.
When oversight fails
Oversight fails quietly: approvals get faster, departures fall towards zero, reasons become formulaic, seeded cases pass, and contestations succeed on grounds the overseers could have seen. Two or more of these in one group for two consecutive periods are, by this book's default, a finding. Following the asymmetry of Chapter 20, the owner records the finding and chooses among five measures of rising strength.
- Fix the design. Remove friction that makes acceptance easier than departure, add independent information, block approval until flags are resolved, and present the case before the proposal so that review does not start from the AI's answer (F76).
- Lower the volume. Plan more time, add overseers, close postings at capacity or triage by need for judgement.
- Train and practise with the group, using its own seeded-case results.
- Return to a lower degree: from Level 3 Bounded to Level 2 Supervised for allocation, from Level 2 Supervised to Level 1 Assisted for rosters, and for an M3 input found decisive in practice, suspension until the decision in the case is real, as Chapter 8 prescribed.
- Stop, through the stop path of Chapter 20, where harmful decisions have passed and the cause is not understood. Article 26(5) of the AI Act requires a deployer with reason to consider that a high-risk system presents a risk within the meaning of Article 79(1) to inform the provider and the market surveillance authority and to suspend its use (1, European Union, 2024).
Decisions taken while oversight was failing are reviewed. For M3 Consequence decisions in the period, the owner offers each person concerned a fresh decision by an overseer with the time and information the class requires, recorded as contestation records under Chapter 27 whether or not the person had contested. The function owner answers for the conditions, under Chapter 20's rules on Q2, and the overseers who worked within them are not made the moral crumple zone.
Worked example: oversight of TalentLens rankings at Hansa Mutual
Illustrative. Hansa Mutual's recruiters decide on every applicant TalentLens ranks, at Level 1 Assisted under DLG-HM-REC-01 version 1.3, which requires them to read at least 20 per cent of the applications ranked below the shortlist and a monthly blind review of 50 rejected applications, within the cap of twelve reviews an hour. The metric OQM-HM-REC-01 was agreed with the Konzernbetriebsrat and consulted in Poland with the company trade union organisation and the employee council. The first oversight record covers the Polish service-centre recruitment team.
# oversight/OVR-HM-REC-2027-Q1-PL.yaml (illustrative)
id: OVR-HM-REC-2027-Q1-PL
profile: DLG-HM-REC-01              # version 1.3
class: HM-M3-HIRE-SCREEN            # DRF-HM-01
recorded_degree: Level 1 Assisted
period: {from: 2027-01-01, to: 2027-03-31}
scope: service-centre recruitment team, Poland
owner: role:chief-hr-officer
metric: OQM-HM-REC-01
aggregation: team of nine recruiters; no figure per recruiter
excluded_uses: [M2 Evaluation of recruiters, M3 Consequence for recruiters]
figures:
  applications_ranked: 3840
  rejected: 3310
  opened_before_rejection_below_cut: 0.24
  median_seconds_open_to_reject_below_cut: 38
  median_minutes_shortlist_decision: 4
  reviews_per_recruiter_hour_peak: 19
  departures_from_ranking: 0.02
  blind_review: {sampled: 150, would_have_advanced: 21, rate: 0.14}
  seeded_applications: {placed: 6, advanced_or_flagged: 3, rate: 0.5}
  contestations: {received: 4, decision_changed: 1}
thresholds:
  median_seconds_open_to_reject_min: 120
  reviews_per_recruiter_hour_max: 12
  departures_min: 0.05
  blind_review_advance_max: 0.10
  seeded_catch_min: 0.85
classification: decisive in practice below the cut
actions:
  decision_record: AIDR-0680
  profile_change: DLG-HM-REC-01 version 1.5   # after version 1.4, the equality block of AIDR-0678 (Chapter 24)
  measures:
    - Every application meeting the published mandatory requirements is opened before rejection
    - Case view shows the application before the rank and the ranking reasons
    - Postings close at the volume the team can read at twelve reviews an hour
    - Two seeded applications a month; a gate withdraws any seed before an interview slot or offer
    - Blind-review disagreements go to the owner of HR-REC-CRIT-2026-01
Under seasonal volume, Level 1 Assisted drifted, as Chapter 7 feared. Recruiters opened just over the required fifth of the applications below the cut and rejected those in a median of 38 seconds; the rest were rejected on the rank alone; the blind review would have advanced one in seven of the rejected; and half of the seeded applications, synthetic profiles that met every requirement but ranked low, were missed. The time spent before rejecting a candidate was the signal, and the volume set it: nineteen reviews per recruiter-hour at peak against a cap of twelve. AIDR-0680 records the changes in actions and publishes them in April 2027 as version 1.5 of the profile, and the German graduate team, whose figures were within thresholds, adopts the same case view so that both markets run one configuration. Thomas Brandt agreed to the metric on condition that no recruiter's figure is shown to anyone but the recruiter, and the excluded_uses field writes that condition down.
What is observable, expected and speculation
Automation bias, complacency and selective adherence are observable in experiments and reviews, and rubber-stamping at volume is observable in reported cases and in organisations' own records, such as the Dutch sales unit of Chapter 8. The oversight record and metric for management systems are this book's proposal. Their adoption is expected where a decided instrument requires evidence of oversight: Article 26(2) applies to Annex III systems from 2 December 2027, and the Platform Work Directive had to be transposed by 2 December 2026. Their acceptance by works councils is expected where figures are reported at team level and excluded from the evaluation of overseers. Whether courts and supervisors will read an oversight record as evidence that a decision was human, or that it was not, is speculation until the first cases are decided.
Across the degrees of delegation
Table 26.1 shows the human role, what can be sampled and the design variables at each degree.
| Degree of delegation | Human role | Can it be sampled | Design variables | Permitted for M3 Consequence |
|---|---|---|---|---|
| Level 0 Advisory | The person decides; the system comments | Not needed | Whether the comment is read | Yes |
| Level 1 Assisted | The person decides each case; the system ranks or drafts parts | No | Case view before proposal, time, independent information | Yes; the ceiling for adverse decisions |
| Level 2 Supervised | The person approves or changes each proposal | No for the case; yes for the system | Volume, time, departures, seeded cases | Yes, for decisions that are not adverse |
| Level 3 Bounded | The person sets and watches the rules; may reassign | Yes | Rules outside the model, samples, seeds, reassignment rate | No |
| Level 4 Autonomous | None in the instance | Only the outcomes | Outcome monitoring and the stop path | Never |
Table 26.1: Oversight across the degrees of delegation.
The usage mode determines where the evidence comes from. A Mode 4 built AI application such as ShiftWise or TalentLens logs what the overseer opened and when, if the tender required it; a Mode 5 autonomous production agent such as the claims-triage agent logs its own actions, and team leaders' reassignments become Management Decision Records; a manager who pastes output from a Mode 1 conversational assistant or a Mode 2 embedded workplace assistant into a decision leaves no oversight trace, which is why Chapter 20 kept such use within the manager's own rights.
Nordvik Region and Hansa Mutual
At Nordvik Region, the oversight record showed Ingrid Halvorsen that some unit managers approved a four-week roster in under two minutes and that rest-rule flags could be closed in bulk. She asked why the design allowed it, not who did it. AIDR-0630 blocks approval until every flag is resolved, plans two hours per roster, removes missed seeds at publication, and requires AI literacy and oversight training before any unit of the second home-care wave goes live in the third quarter of 2027. Mikael Strand sees his own figures and helped design the seeds: a newly employed care assistant alone at a two-person visit, and three late-early changes in one week. OQM-NR-ROS-01 is negotiated with the unions and reported to the central work-environment committee, aggregated across the wave.
At Hansa Mutual, AIDR-0680 extends OQM-HM-CLM-01 from handlers' review of agent output to team leaders' oversight of the claims-triage agent's allocation: reassignments with recorded reasons, beginning with MDR-HM-0001, and seeded allocations a careful team leader should catch within a working day, such as a complex claim allocated to a handler in her first month. Because Jana Petersen is the only team leader in her team, the figures are reported across the Hamburg claims department, and Thomas Brandt agreed on condition that no individual team leader's figure is shown.
The difference lies in where oversight sits. Nordvik's managers decide each roster, so its record tests the decision in the case. Hansa's team leaders oversee an agent at Level 3 Bounded, so its claims record tests oversight of the system, while its recruiting record tests a decision in the case that had drifted.
Summary
This chapter asked when the human in the chair is a decider and when a signature. Policies that merely require a human in the loop rest on an assumption the evidence does not support: automation bias and complacency occur in naive and expert users and are not prevented by training alone, people adhere selectively to advice that fits their stereotypes, and they can also discount sound advice after seeing it err. Data protection law treats a human without influence as absent, and SCHUFA reaches the score on which a decision draws strongly.
Oversight is real when six conditions hold: time per decision, authority to deviate, information independent of the system, a measured deviation rate, consequences that do not punish deviation, and a stop path, anchored in Articles 14(4) and 26(2) of the AI Act, Article 22(3) of the GDPR and Article 10 of the Platform Work Directive. Oversight of the system can be sampled and makes Level 3 Bounded safe for M1 Direction; the decision in an individual M3 Consequence case cannot be sampled and is required in every case.
The oversight record states who oversaw, what they saw, what they did and with what authority. The oversight-quality metric measures time, departures, seeded cases, reversals and stops at team level and is never used in the M2 Evaluation of overseers. The answer to Q9 is that individual decisions cannot be overseen at hundreds an hour: the class must be honestly reclassified with oversight of the system, or its volume reduced to what people can read. When oversight fails, the owner fixes the design, lowers volume, trains, returns the class to a lower degree or stops the system, and reviews the decisions taken meanwhile.
Nordvik Region changed its approval screen rather than its managers; Hansa Mutual changed its recruiters' volume and case view. Chapter 27 turns to the person overseen: how a worker learns what was decided, contests it and has it corrected, and why a contestation is often the first signal that oversight has failed.
Sources
- European Parliament and Council of the European Union (2024). Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). Official Journal of the European Union. (1, European Union, 2024)
- European Parliament and Council of the European Union (2026). Regulation (EU) 2026/1744 amending Regulations (EU) 2024/1689, (EU) 2018/1139 and (EU) 2023/1230 (Digital Omnibus on AI). Official Journal of the European Union. (2, European Union, 2026)
- European Parliament and Council of the European Union (2016). Regulation (EU) 2016/679 (General Data Protection Regulation). Official Journal of the European Union. (5, European Union, 2016)
- Federal Republic of Germany (2001). Betriebsverfassungsgesetz (BetrVG). Gesetze im Internet. (9, Germany, 2001)
- Bainbridge, L. (1983). Ironies of automation. Automatica, 19(6), 775–779. (24, Bainbridge, 1983)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors, 52(3), 381–410. (25, Parasuraman & Manzey, 2010)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 2. (41, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 4. (43, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. The Architecture as Code Series, Book 5. (44, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect: Role, Craft and Career in the Age of AI in European Enterprises and Public Authorities. The Architecture as Code Series, Book 6. (46, Nordqvist, 2026)
- European Parliament and Council of the European Union (2024). Directive (EU) 2024/2831 on improving working conditions in platform work. Official Journal of the European Union. (47, European Union, 2024)
- Article 29 Data Protection Working Party (2018). Guidelines on Automated individual decision-making and Profiling for the purposes of Regulation 2016/679 (WP251rev.01). (61, Article 29 Data Protection Working Party, 2018)
- Court of Justice of the European Union (2023). Judgment of 7 December 2023, OQ v Land Hessen (SCHUFA Holding (Scoring)), Case C-634/21. (63, CJEU, 2023)
- Skitka, L. J., Mosier, K. L. & Burdick, M. (1999). Does automation bias decision-making? International Journal of Human-Computer Studies, 51(5), 991–1006. (155, Skitka et al., 1999)
- Dietvorst, B. J., Simmons, J. P. & Massey, C. (2015). Algorithm aversion: People erroneously avoid algorithms after seeing them err. Journal of Experimental Psychology: General, 144(1), 114–126. (157, Dietvorst et al., 2015)
- Logg, J. M., Minson, J. A. & Moore, D. A. (2019). Algorithm appreciation: People prefer algorithmic to human judgment. Organizational Behavior and Human Decision Processes, 151, 90–103. (168, Logg et al., 2019)
- Elish, M. C. (2019). Moral Crumple Zones: Cautionary Tales in Human-Robot Interaction. Engaging Science, Technology, and Society, 5, 40–60. (170, Elish, 2019)
- Green, B. (2022). The flaws of policies requiring human oversight of government algorithms. Computer Law & Security Review, 45, 105681. (178, Green, 2022)
- Alon-Barkat, S. & Busuioc, M. (2023). Human–AI Interactions in Public Sector Decision Making: "Automation Bias" and "Selective Adherence" to Algorithmic Advice. Journal of Public Administration Research and Theory, 33(1), 153–169. (179, Alon-Barkat & Busuioc, 2023)
- Rucker, P., Miller, M. & Armstrong, D. (2023). How Cigna Saves Millions by Having Its Doctors Reject Claims Without Reading Them. ProPublica, co-published with The Capitol Forum. (245, Rucker et al., 2023)